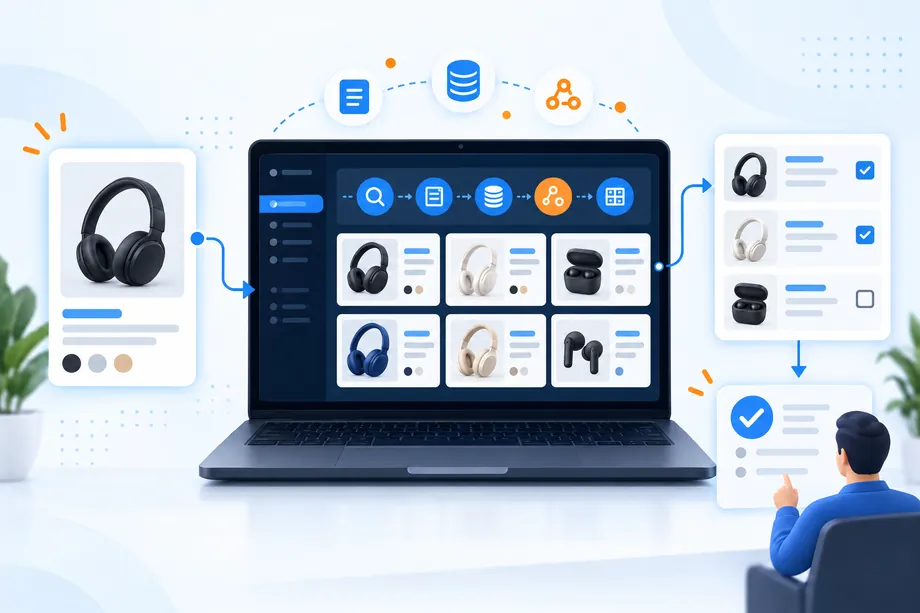
Competitor discovery often starts with a familiar request: take one known ASIN and find the products a shopper is likely to compare with it. The hard part is not collecting a list. It is avoiding a list that quietly mixes substitute products, accessories, duplicate variants, adjacent categories, and false positives. A disciplined amazon similar products api workflow treats related listings as research candidates. It does not label every returned ASIN as a competitor, and it does not infer demand, sales, margin, or commercial intent from the association alone.
For developers, catalog teams, and agencies, traceability is essential. Preserve the seed ASIN, marketplace, collection time, and discovery source, then add enrichment and a review state.
Quick Answer: Build a Candidate Queue, Not a Verdict
Start with a tightly defined seed ASIN and marketplace. Collect a bounded set of related products, keep the returned association intact, enrich only the records that meet your scope rules, and send ambiguous cases to review. This sequence makes the workflow repeatable across product categories without pretending that a recommendation signal is a complete market-research answer.
| Stage | Output | Decision it supports |
|---|---|---|
| Discover | Related ASIN candidates | Which listings should enter research? |
| Normalize | Consistent candidate records | Can records be compared and audited? |
| Enrich | Product and offer context | Which candidates fit the chosen scope? |
| Review | Accepted, ambiguous, or excluded state | What can downstream analysis safely use? |
What Is an Amazon Similar Products API?
An Amazon similar products API is an ASIN-anchored discovery method. Instead of guessing a keyword query, you start with a known product and receive the listings Amazon associates with that source in the same marketplace. In Easyparser, the Similar Products operation returns a source product plus related items with compact catalog context such as ASIN, title, brand, category, and image. You can request a limited set of 10, 50, or 100 related products.
Define the Comparison Scope Before You Collect Data
A seed ASIN has no universal competitor set. The same listing can be compared differently by a marketplace analyst, a brand-protection team, a sourcing group, or a product team building a recommendation feature. Write the scope down before calling any endpoint. At minimum, define the marketplace, source ASIN list, category boundaries, excluded brands, duplicate policy, and the commercial question the queue will support.
A private-label team might retain only candidates in the same terminal category and price band after enrichment. A catalog team might keep every unique ASIN for taxonomy work. An agency might exclude the client brand, bundles, and accessories. These are business rules, not guarantees of similarity.
- Marketplace: Store the Amazon domain with every source and candidate record. The same ASIN concept can have different listing context across marketplaces.
- Source set: Use a documented seed list rather than an untracked assortment of product pages.
- Inclusion rule: State whether category, brand, title terms, variation type, or visible offer context must match.
- Exclusion rule: Decide how to handle accessories, refills, bundles, parent-child variants, and your own catalog.
- Review owner: Assign who can change an ambiguous record from pending to accepted or excluded.
Expand a Seed ASIN into a Bounded Candidate List
Begin with one seed ASIN per request so the relationship stays easy to inspect. Choose a small limit for an exploratory test and a larger limit only after you know how your review capacity, category rules, and storage model will handle the results. The source product should remain attached to every candidate, even if you later deduplicate the same candidate discovered from several seeds.
When you build an Amazon similar products API pipeline, preserve the raw association before adding opinionated labels. A practical naming pattern is similarity_source = amazon_associated. This lets an analyst distinguish a product that appeared through a related-products response from one discovered by search, a storefront crawl, or a manually supplied list. Provenance becomes especially important when two discovery methods surface the same ASIN for different reasons.
Similar Products Request Example (Python)
Install the Python requests package and replace YOUR_API_KEY with your dashboard key. Send a GET request to the real-time endpoint with operation=SIMILAR_PRODUCTS, platform=AMZ, and domain=.com for Amazon US. Choose similar_limit from 10, 50, or 100; this is a maximum, not a guaranteed count. Keep the key out of version control and request logs.
import requests
params = {
"api_key": "YOUR_API_KEY",
"platform": "AMZ",
"operation": "SIMILAR_PRODUCTS",
"domain": ".com",
"asin": "B00KTLXB4C",
"similar_limit": "10"
}
response = requests.get(
"https://realtime.easyparser.com/v1/request",
params=params, timeout=60
)
response.raise_for_status()
payload = response.json()
if payload.get("request_info", {}).get("success") is not True:
raise RuntimeError("Easyparser request failed")
product = payload["result"]["product"]
for related in product["similar"]:
print(product["asin"], related["asin"], related.get("brand"))
Similar Products Response Example (JSON)
This shortened excerpt comes from Easyparser's published sample for the same ASIN. It shows one of the sample's 10 related products; other items, request metadata, credit fields, and some source-product fields are omitted. It is not a new live API result.
{
"request_info": {
"success": true,
"status_code": 200
},
"request_parameters": {
"asin": "B00KTLXB4C",
"similar_limit": "10",
"type": "SIMILAR_PRODUCTS"
},
"result": {
"product": {
"asin": "B00KTLXB4C",
"title": "NIVEA Cocoa Butter Body Lotion for Dry Skin with Hyaluronic Acid 16.9 Oz",
"brand": "NIVEA",
"category": "Skin Care/Body/Moisturizers",
"similar": [
{
"asin": "B08NGDVKBK",
"brand": "NIVEA",
"category": "Skin Care/Body/Moisturizers",
"image": {
"id": "41nGBeo-UBL",
"link": "https://m.media-amazon.com/images/I/41nGBeo-UBL.jpg",
"variant": "MAIN"
},
"title": "NIVEA Cocoa Butter Body Lotion for Dry Skin Hyaluronic Acid 33.8 Fl Oz"
}
]
}
}
}
The source ASIN is result.product.asin; candidates are in result.product.similar. Read each candidate's asin, title, brand, category, and image.link. Notice that the request uses operation but the response echoes it as request_parameters.type. No price or seller-offer fields are included.
Use a Reviewable Candidate Record
The original response is not always the best format for a database, spreadsheet, queue, or BI model. Normalize it into a record that can answer basic audit questions: where did the candidate come from, when was it collected, which product seeded it, and what happened next?
Map source_asin to product["asin"] and candidate_asin to each related["asin"]. Add your request marketplace, a collection timestamp, similarity_source = amazon_associated, and review_state = pending. These last fields belong to your storage model, not the API response.
Add raw catalog fields, a request ID, and a payload reference when retention policy permits. Timestamp observations rather than overwriting them silently, so reviewers can distinguish current listing context from the evidence used in a prior decision.
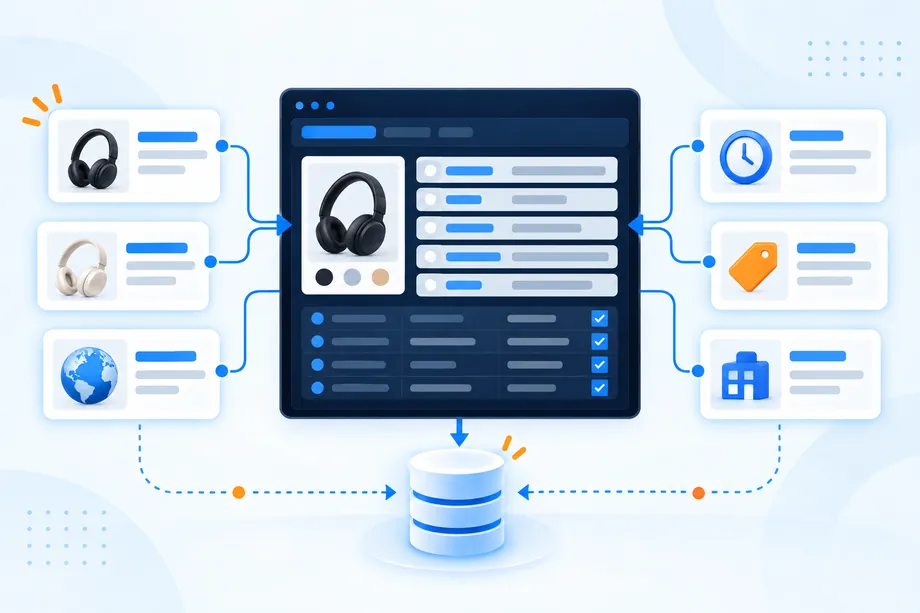
Enrich Candidates with Product and Offer Context
Similarity tells you which candidates to inspect. Enrichment tells you what they are. For each candidate that passes your first scope filter, use the Product Detail API to collect public listing context such as title, brand, category, images, specifications, visible price, availability, and variations. This step lets you compare like with like instead of comparing a product page title with an unexamined association.
Use offer-level data only when the research question requires it. The Product Offer API can supply current seller, price, fulfillment, shipping, and Buy Box context. That is relevant for an operations team reviewing marketplace competition, but it is not necessary for every candidate discovery job. Separating detail enrichment from offer enrichment controls cost, reduces unnecessary data collection, and keeps the initial queue focused.
A useful enrichment order is: validate the candidate ASIN and marketplace, collect detail context, classify product relationship, then request offer context if the candidate remains relevant. If a title, category, or variation rule excludes the candidate, record the reason and stop there. This makes the pipeline explainable and avoids treating expensive or volatile fields as mandatory for every record.
Separate Similarity Signals from Commercial Validation
Teams often overstate what related-product data can prove. A similarity signal may indicate that Amazon groups items in a related context, but it cannot establish market demand, unit sales, conversion, profitability, or that another brand is a direct commercial competitor. Those claims require separate evidence, definitions, and validation methods.
Store three separate decisions: comparability to the seed, compliance with category and brand rules, and relevance to the operational question. A candidate can be similar but not comparable, comparable but excluded by policy, or relevant but still pending review.
| Signal | What it can help with | What it cannot prove |
|---|---|---|
| Related ASIN association | Starting a candidate queue | Direct competition or demand |
| Product detail context | Comparing title, brand, category, variations, and visible attributes | Sales or profitability |
| Offer context | Reviewing current visible seller and fulfillment conditions | Long-term pricing strategy or margin |
| Human review | Applying internal category and policy knowledge | Objective certainty when evidence is incomplete |
Deduplicate Variants and Record Marketplace Context
Variants create one of the most common quality problems in discovery queues. A parent listing, color variation, size variation, multipack, replacement part, and bundle can all look related while serving different customer needs. Do not collapse records only because titles look similar. Use a combination of ASIN, parent or child relationship when available, brand, category path, title normalization, and product attributes. Preserve the original source link between the seed and every raw candidate even if the normalized model groups them later.
Store marketplace on every record. Naming, availability, delivery context, and catalog organization can differ by domain. Keep cross-market observations separate until a defined mapping rule and reviewer establish a match.
Route Ambiguous Candidates to Human Review
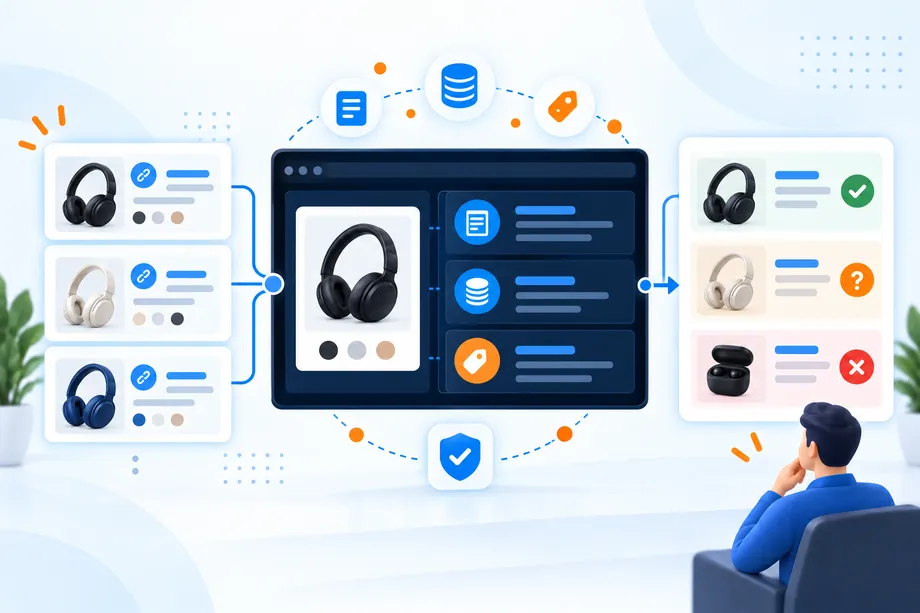
Automation is most valuable when it makes review faster, not when it hides uncertainty. Create three simple outcomes: accepted, ambiguous, and excluded. Accepted records satisfy documented rules. Excluded records have a reason such as accessory, duplicate, out-of-scope category, or owned brand. Ambiguous records have conflicting or incomplete signals and should remain visible to a reviewer.
Show reviewers the seed and candidate ASINs, marketplace, raw title and category, normalized labels, collection time, exclusion triggers, and relevant enrichment. Preserve decisions and reasons so recurring accessory terms or variation patterns can improve future rules.
Choose Real-Time or Bulk Processing Deliberately
Real-time collection fits interactive applications, on-demand analyst work, and small validation tests where the response should be evaluated immediately. Bulk processing fits larger ASIN sets, scheduled refreshes, and backlog-oriented pipelines where an asynchronous job and callback can deliver results later. The right choice follows the work pattern, not the perceived importance of the request.
Test a small seed set in real time before moving repeated collection to bulk. Store job IDs, submission and completion times, and callback status. Keep submitted requests, received responses, and reviewed candidates as distinct operational states.
Build Quality Checks into the Request and Response Path
A discovery workflow should fail safely. Validate the input ASIN format, marketplace, selected result limit, and project scope before submitting a request. After a response arrives, check that the source ASIN matches the requested seed, that candidates are present when expected, and that each candidate has an ASIN before it can enter the normalized table. Missing optional catalog fields should be recorded as missing, not silently replaced with a guessed value.
Use a status model that distinguishes request failure, successful empty response, partial record, and review pending. Empty data is not automatically an error, and a returned candidate with no title or category is not necessarily invalid. The important point is that downstream users can see which condition occurred. That distinction prevents a dashboard from treating an API timeout, an empty candidate set, and an excluded record as the same zero.
| Check | Why it matters | Safe response |
|---|---|---|
| Seed ASIN and marketplace match | Protects source-to-candidate traceability | Quarantine mismatched records |
| Candidate ASIN exists | Supports later enrichment joins | Keep raw response and mark partial |
| Required scope fields are present | Applies category and brand rules consistently | Route to ambiguous review |
| Duplicate relationship detected | Prevents repeated analysis of the same candidate | Merge only with provenance retained |
| Detail or offer context is stale | Prevents outdated commercial interpretation | Refresh only the accepted candidate |
A Practical 30-Day Discovery Pilot
Week one: choose seeds from one marketplace and document scope. Week two: collect, normalize, and review a sample. Week three: enrich accepted and ambiguous records only where needed. Week four: measure duplicate rate, review time, acceptance rate, and exclusion reasons.
Use pilot feedback to improve rules: enrich missing category context, filter recurring accessories, and store repeated seed-to-candidate relationships without counting each occurrence as a new competitor.
Conclusion: Turn Related Products into Defensible Research Inputs
The amazon similar products api is most useful when it expands a known ASIN into a controlled research queue. Use the similarity association to discover candidates, retain marketplace and timestamp context, enrich records only when needed, and make review outcomes explicit. Easyparser can provide the structured starting point, while your scope rules and human review determine whether a candidate is relevant to your actual competitive-intelligence workflow.
Start monitoring your competitors for free
Start Your Free Trial100 free credits, no credit card required.